SRESchool.in: Learn Site Reliability Engineering Through Practical Skills
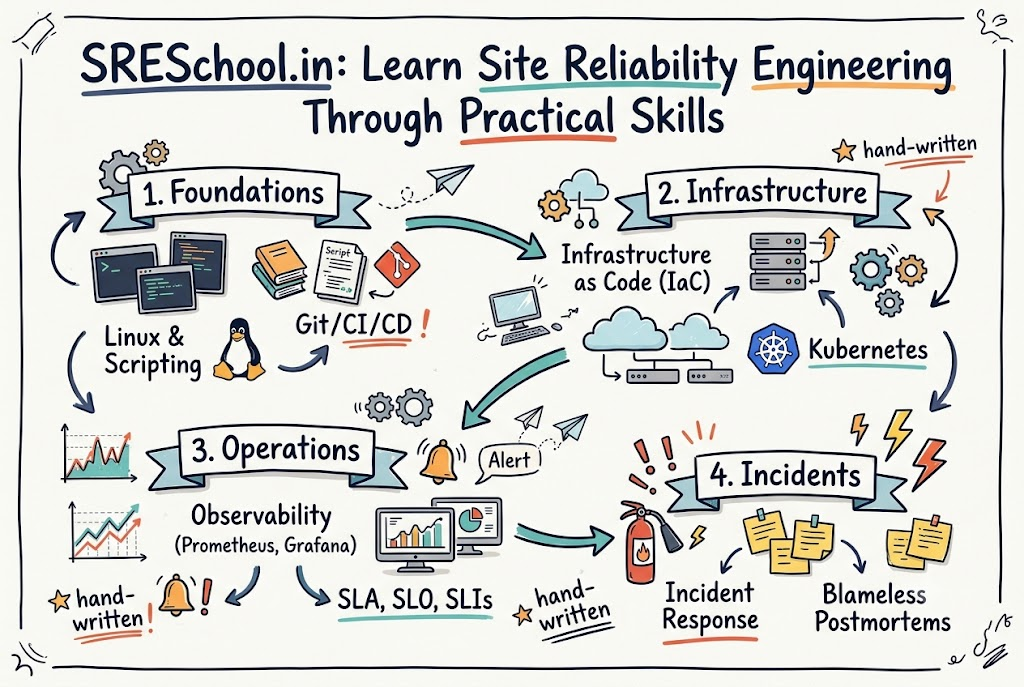
Introduction
A production system can look healthy one moment and start causing trouble the next. A deployment may introduce errors, traffic may grow faster than expected, or a small infrastructure problem may affect several services. Engineers need more than troubleshooting skills to handle these situations. They need a reliable way to measure system health, respond to failures, automate routine work, and improve the service over time.
Site Reliability Engineering brings these activities together. It combines software engineering, infrastructure management, monitoring, automation, cloud technology, and operational practices.
SRESchool.in focuses on these areas and provides learning resources around SRE concepts, tools, production systems, observability, incident management, and reliability. Whether someone is beginning an SRE Course or strengthening existing technical knowledge, a structured learning approach can make complex subjects easier to understand.
Why Engineers Need Site Reliability Engineering
Software teams often focus on building and releasing features. Production teams must also make sure those features continue working when real users interact with them.
That difference creates many reliability challenges. Applications can become slow, infrastructure can reach resource limits, deployments can fail, and alerts can overwhelm engineering teams.
SRE provides a framework for managing these problems.
Instead of asking only whether an application works, SRE encourages engineers to ask:
- How reliably does the service work?
- How should the team measure reliability?
- What level of failure can users tolerate?
- How quickly can engineers detect problems?
- How can the team recover from incidents?
- Which repetitive tasks can automation handle?
- What should engineers improve after an incident?
This approach makes reliability an ongoing engineering responsibility.
What SRE Training Can Teach You
A well-designed SRE Training program should build understanding gradually. Beginners need strong fundamentals, while experienced engineers may want deeper production practices.
Common learning areas include:
- Site Reliability Engineering principles
- Monitoring and alerting
- Metrics, logs, and traces
- Service Level Indicators
- Service Level Objectives
- Service Level Agreements
- Error budgets
- Incident management
- Incident response
- Automation
- Capacity planning
- Cloud reliability
- Infrastructure
- Troubleshooting
- Production operations
For instance, learning about monitoring becomes more useful when an engineer understands what to monitor and why. A dashboard filled with dozens of charts does not automatically provide useful operational information.
Good training helps learners connect technical signals with actual service behavior.
What Makes SRE Certification Worth Understanding?
SRE Certification gives professionals a structured way to study and assess their understanding of reliability engineering. However, certification programs can differ significantly.
One provider may emphasize theoretical concepts, while another may include practical assessments or different subject areas. Requirements and recognition also vary.
Before choosing a certification, review:
- Eligibility requirements
- Exam structure
- Topics covered
- Practical components
- Renewal requirements
- Provider information
- How the certification fits your learning goals
Certification can support professional development, but it should not become the only learning objective.
An engineer still needs practical skills in monitoring, troubleshooting, automation, infrastructure, deployments, and incident response. Certification does not guarantee employment, promotions, salary increases, or any specific career result.
How to Pick the Right SRE Course
The right SRE Course depends on what you already know.
A beginner may need Linux, networking, cloud, software, and infrastructure fundamentals before moving into advanced reliability topics. An experienced DevOps professional may already understand these areas and need more focus on SLOs, observability, incident response, and reliability strategy.
Check the curriculum before enrolling.
A useful course may include:
| Learning Area | Useful Focus |
|---|---|
| Fundamentals | Core SRE concepts and principles |
| Monitoring | System health, metrics, and alerts |
| Observability | Logs, traces, metrics, and investigation |
| Reliability | SLOs, SLIs, SLAs, and error budgets |
| Incidents | Detection, response, recovery, and review |
| Automation | Reducing repetitive operational tasks |
| Cloud | Reliability, scaling, and infrastructure |
| Troubleshooting | Finding and understanding failures |
| Practical Work | Labs, projects, or technical exercises |
Course quality depends on the actual curriculum and learning experience, so learners should evaluate the details rather than rely only on course titles.
Site Reliability Engineering Training and Practical Learning
Site Reliability Engineering Training becomes more useful when it explains how concepts work in realistic situations.
Imagine a service that responds correctly during normal traffic but slows down when demand increases. An SRE learner can investigate latency, resource usage, dependencies, logs, and traces to understand what changed.
That exercise connects several concepts at once.
Practical training can help learners understand how to:
- Define reliability objectives
- Select useful service indicators
- Create meaningful alerts
- Investigate incidents
- Automate repeatable work
- Monitor infrastructure
- Improve deployment processes
- Plan for capacity
The aim should remain practical understanding rather than memorizing definitions.
How Site Reliability Engineering Certification Fits Into Professional Learning
Certification can complement broader SRE education. Learners can use certification objectives as a study framework and then strengthen those concepts through practical exercises.
Important areas may include:
- Reliability concepts
- SLO and SLI design
- Error budgets
- Monitoring
- Observability
- Incident response
- Automation
- Cloud systems
- Infrastructure
- Production troubleshooting
The certification provider determines the actual requirements, so learners should check those requirements directly.
Practical experience remains valuable because real systems rarely behave exactly like textbook examples. Engineers need to interpret incomplete information, communicate during incidents, and make careful decisions under pressure.
Learning SRE Through Tutorials
An SRE Tutorial can help break complicated subjects into manageable lessons.
Instead of studying everything at once, learners can follow a logical progression:
Begin with reliability fundamentals.
Understand why teams measure service health and define reliability objectives.
Move into observability.
Learn how metrics, logs, and traces provide information about system behavior.
Study incidents.
Understand detection, response, recovery, communication, and postmortems.
Practice automation.
Identify repeated tasks and determine which ones can benefit from automation.
Explore infrastructure.
Study cloud systems, containers, Kubernetes, Terraform, and related technologies according to your learning needs.
This gradual method can make SRE easier for beginners while still giving experienced professionals areas to explore further.
Understanding the Different Types of SRE Tools
SRE Tools support many parts of production operations. Engineers often use several categories together because no single tool handles every reliability task.
| Tool Category | Common Purpose |
|---|---|
| Monitoring | Track application and infrastructure health |
| Metrics | Measure numerical system signals |
| Logging | Investigate recorded events |
| Tracing | Follow requests across services |
| Alerting | Notify teams about important conditions |
| Incident Management | Coordinate incident response |
| Infrastructure Management | Manage technical resources |
| Infrastructure as Code | Define infrastructure through configuration |
| Deployment | Support consistent software releases |
| Troubleshooting | Investigate system problems |
Tool selection should follow technical requirements.
An organization running a large container platform may have different needs from a small application team. Architecture, cloud provider, team experience, budget, and operational complexity all influence the decision.
SRE Best Practices That Teams Can Apply
SRE Best Practices focus on making reliability measurable and manageable.
Teams can improve reliability by:
- Defining clear service goals
- Measuring meaningful system indicators
- Setting appropriate SLOs
- Using error budgets
- Reducing unnecessary alerts
- Improving observability
- Automating repetitive work
- Preparing incident response plans
- Reviewing production failures
- Improving deployment processes
- Planning capacity
- Testing recovery procedures
Suppose engineers receive alerts for every small fluctuation. They may start ignoring notifications because the volume becomes too high.
The team can review alert rules and focus notifications on conditions that require human action.
Another example involves manual deployments. If engineers repeatedly perform the same steps, automation may reduce errors and improve consistency.
The right approach depends on the service and its risks.
What an SRE Engineer Does
An SRE Engineer helps teams maintain reliable production systems. The job often combines software engineering, infrastructure, cloud, monitoring, automation, and operations.
Responsibilities may include:
- Building automation
- Improving monitoring
- Investigating production incidents
- Managing infrastructure
- Supporting deployments
- Reviewing system performance
- Planning capacity
- Improving reliability
- Reducing operational toil
- Working with development teams
An SRE Engineer may write software one day and investigate an infrastructure problem the next.
People can reach SRE roles through different backgrounds. Software development, DevOps, cloud engineering, system administration, infrastructure, and platform engineering can all provide useful foundations.
No single career route fits every SRE professional.
SLI, SLO, SLA, and Error Budget in Simple Terms
These four concepts help teams discuss reliability with more clarity.
Service Level Indicator
An SLI measures a service characteristic. Examples include request success rate, latency, or availability.
Service Level Objective
An SLO defines the target that a service should meet for a selected SLI.
Service Level Agreement
An SLA represents an agreement between a provider and customer. It can describe expected service levels and related commitments.
Error Budget
An error budget represents the amount of unreliability allowed by an SLO.
For example, a team can define a reliability objective for an important service. If the service consumes too much of its error budget, the team may choose to focus more engineering effort on reliability.
Teams should not copy a reliability target simply because another organization uses it. The appropriate target depends on user expectations, business requirements, architecture, and acceptable risk.
Monitoring Versus Observability
Monitoring and observability support different parts of system understanding.
Monitoring helps engineers watch known signals and identify conditions that require attention. Observability helps engineers investigate system behavior, including problems they did not fully anticipate.
Engineers commonly work with:
- Metrics
- Logs
- Traces
- Alerts
- Dashboards
- Application performance data
- Infrastructure signals
Consider an application that suddenly becomes slow.
Metrics might reveal increased response time. Logs might show application errors. Traces might identify a dependency that takes too long to respond.
Combining these signals gives engineers more information for troubleshooting.
A Practical Approach to Incident Management
Every production team needs a plan for dealing with failures.
Incident management usually involves several stages:
- Detect the problem.
- Confirm the impact.
- Notify the appropriate responders.
- Investigate the issue.
- Reduce the user impact.
- Restore normal operation.
- Communicate important information.
- Document the event.
- Review the incident.
- Apply useful improvements.
Postmortems play an important role after significant incidents. Teams can use them to identify technical weaknesses, monitoring gaps, unclear procedures, deployment risks, or automation opportunities.
A constructive postmortem focuses on learning and system improvement rather than blaming an individual.
Using Automation to Control Operational Work
Repeated manual work can consume engineering time and introduce avoidable mistakes.
SRE teams can examine repetitive activities and identify suitable opportunities for automation.
Examples include:
- Routine health checks
- Deployment steps
- Infrastructure provisioning
- Monitoring configuration
- Recovery procedures
- Data collection
- Repeated maintenance tasks
Automation needs careful design. An unsafe automated process can create larger problems than the manual process it replaces.
Engineers should understand failure conditions, permissions, rollback options, and expected outcomes before automating critical operations.
The objective is simple: remove unnecessary repetitive work while keeping appropriate human control over important decisions.
Cloud Reliability and Distributed System Challenges
Cloud environments contain many interconnected components. Applications may depend on databases, networks, storage, containers, external services, and other internal systems.
Distributed systems introduce additional complexity because one component can fail while other components continue operating.
SRE professionals should understand:
- Dependencies
- Scaling
- Resource limits
- Network behavior
- Availability
- Capacity
- Failure recovery
- Monitoring
- Observability
For example, an application may appear healthy while one dependent database experiences high latency. Users may still notice the impact even though the application process itself remains active.
SRE encourages engineers to understand these relationships instead of examining individual components in isolation.
Kubernetes and Terraform for Reliability Work
Kubernetes manages containerized workloads and can help teams operate applications across clusters. It supports areas such as workload scheduling, service management, scaling, and container operations.
Terraform supports infrastructure as code. Engineers can describe infrastructure through configuration and manage changes through a repeatable workflow.
Both technologies can support reliability engineering when they fit the organization’s environment.
However, SRE does not require every organization to use Kubernetes or Terraform. A smaller application may use a different architecture, while another organization may rely heavily on container platforms and infrastructure automation.
The important skill involves understanding the underlying reliability problem and choosing suitable technology to address it.
Building a Personal SRE Learning Plan
A practical learning plan can prevent beginners from trying to learn every SRE topic simultaneously.
Start With Foundations
Learn Linux, networking, databases, applications, infrastructure, and cloud fundamentals.
Add DevOps Skills
Understand source control, CI/CD, containers, deployment processes, and infrastructure management.
Study Core SRE Concepts
Learn SLOs, SLIs, SLAs, error budgets, reliability, and operational toil.
Practice Observability
Work with metrics, logs, traces, dashboards, and alerting.
Learn Incident Response
Practice detecting problems, investigating failures, restoring services, and writing postmortems.
Build Automation Skills
Choose repetitive tasks and create safe automation around them.
Practice With Projects
Create small production-style systems and test their monitoring, deployment, failure handling, and recovery.
This progression allows learners to build knowledge without depending entirely on theoretical study.
SRE Training in India: What Learners Should Focus On
People searching for SRE Training in India can approach the subject from several technical backgrounds.
A software developer may focus on reliability and production operations. A cloud engineer may explore SLOs and incident response. A DevOps professional may deepen knowledge of observability and reliability measurement.
Useful learning areas include:
- Cloud infrastructure
- DevOps
- Software engineering
- Automation
- Monitoring
- Observability
- Infrastructure
- Incident response
- Troubleshooting
- Production systems
When comparing training options, examine the curriculum, practical work, prerequisites, teaching approach, and learning goals.
Training can improve technical knowledge, but it cannot guarantee employment or a particular career outcome.
How SRESchool.in Can Support Your SRE Learning
SRESchool.in centers its learning focus on Site Reliability Engineering and related technical areas. These include cloud reliability, automation, monitoring, observability, incident management, and production systems.
The platform can help learners explore subjects connected with SRE Training, SRE Certification, SRE Courses, SRE Tutorials, SRE Tools, and SRE Best Practices.
Professionals can also connect these subjects with technologies such as DevOps, Kubernetes, Terraform, cloud infrastructure, and automation.
Like any learning platform, the usefulness of a particular course depends on its curriculum and how well it matches the learner’s existing knowledge and goals. Combining structured education with practical projects can create a more complete learning experience.
Why SRE Skills Matter Across Technical Roles
Reliability affects almost every part of a production environment.
Developers need to understand how applications behave after deployment. Cloud engineers need to consider availability and scaling. DevOps professionals work with automation and deployment reliability. Infrastructure engineers manage resources and dependencies. Operations teams respond to incidents and system problems.
SRE provides a common way to think about these challenges.
It encourages teams to measure what matters, automate suitable work, prepare for failure, and improve systems after incidents.
That makes SRE knowledge useful beyond one specific job title.
Frequently Asked Questions About SRESchool.in
1. What is SRESchool.in used for?
SRESchool.in focuses on learning Site Reliability Engineering and related subjects such as cloud reliability, monitoring, observability, automation, incident management, and production systems.
2. What does SRE Training normally teach?
SRE Training may teach SLOs, SLIs, SLAs, error budgets, monitoring, observability, incident response, automation, cloud reliability, capacity planning, troubleshooting, and production operations.
3. Do I need certification to become an SRE Engineer?
No. Certification can support structured learning, but engineers can develop SRE skills through practical experience, software engineering, infrastructure, cloud, DevOps, automation, monitoring, and troubleshooting.
4. How can I choose an SRE Course?
Review the curriculum, prerequisites, practical exercises, monitoring content, observability topics, incident response coverage, automation, troubleshooting, and overall learning format.
5. What does Site Reliability Engineering Training mean?
Site Reliability Engineering Training teaches methods for measuring, managing, and improving system reliability. It can connect SRE theory with practical production engineering situations.
6. Can an SRE Tutorial help someone who is new to reliability engineering?
Yes. Tutorials can introduce concepts gradually and help learners move from basic reliability principles toward monitoring, observability, incident response, automation, cloud systems, and troubleshooting.
7. What are common SRE Tools?
SRE teams may use tools for monitoring, metrics, logging, tracing, alerting, incident management, infrastructure management, infrastructure as code, deployment, and troubleshooting.
8. Which SRE Best Practices should beginners learn first?
Beginners can start with clear reliability goals, useful SLIs and SLOs, effective monitoring, meaningful alerts, incident preparation, postmortems, automation, and capacity planning.
9. What technical knowledge helps an SRE Engineer?
Software development, Linux, infrastructure, cloud, networking, automation, monitoring, observability, troubleshooting, incident response, and production operations can all provide useful foundations.
10. What should I consider when looking for SRE Training in India?
Compare the curriculum, practical exercises, prerequisites, learning format, technical depth, and how well the program matches your existing skills and professional goals.
Final Thoughts
Learning reliability engineering requires a practical mindset. Engineers need to understand not only how systems work but also how those systems behave when traffic increases, dependencies fail, deployments go wrong, or infrastructure reaches its limits.SRE provides useful methods for handling these situations. SLOs and SLIs help teams measure reliability. Observability helps engineers investigate problems. Incident management creates structure during failures. Automation reduces repetitive work, while capacity planning helps teams prepare for changing demand.SRESchool.in provides a focused learning environment for people exploring these areas through SRE Training, SRE Courses, SRE Certification topics, SRE Tutorials, SRE Tools, and SRE Best Practices.The most effective learning path combines structured study with practical experience. Build small systems, monitor them, create failure scenarios, troubleshoot problems, automate suitable tasks, and keep improving your understanding of reliable production engineering.
Leave a Reply